
Nvidia's Next-Generation AI Racks Hit $7.8 Million as Advanced Memory Reshapes Computing Economics
As the cost of high-bandwidth memory reaches 25% of total system expenses, Nvidia's newest data center racks are redefining the financial and technical scale of frontier artificial intelligence.
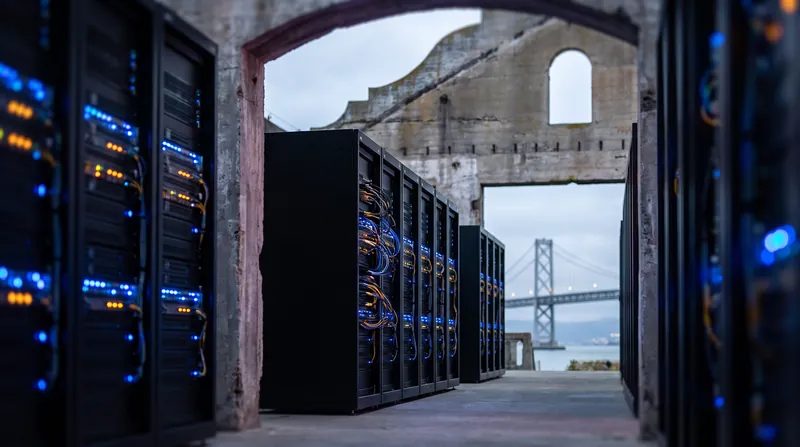
The physical architecture of artificial intelligence is undergoing a massive financial recalibration. Nvidia's next-generation AI server racks—the hyper-dense computing units that power the world's most advanced frontier models—have reached an unprecedented price point of $7.8 million per unit.
This staggering figure represents a significant leap from previous generations, driven not just by the increasing complexity of the graphics processing units (GPUs) themselves, but by a fundamental shift in the underlying bill of materials. The era of cheap data center expansion has officially ended, replaced by an environment where compute density commands an extraordinary premium.[1][2]
The primary culprit behind this soaring price tag is memory. According to industry supply chain analyses, High-Bandwidth Memory (HBM) now accounts for roughly 25% of the total cost of these next-generation systems. In previous computing eras, memory was treated as a relatively commoditized component, a cheap and abundant resource that sat adjacent to the processor.
But modern AI workloads have completely inverted that dynamic. Large language models are fundamentally constrained by how fast they can move data from memory to the processor, creating a desperate need for specialized, ultra-fast memory architectures.
To solve this data-transfer bottleneck, engineers have had to physically stack memory chips on top of one another and package them directly alongside the GPU silicon. This process, known as advanced packaging, is notoriously difficult and yields fewer usable chips than traditional manufacturing. The latest HBM iterations require microscopic precision to align thousands of vertical connections between the stacked memory layers. As a result, the manufacturing complexity has skyrocketed, and the cost of memory has surged to reflect its new status as the critical limiting factor in AI performance.
This architectural shift has created a massive financial windfall for the handful of companies capable of manufacturing these specialized memory chips. South Korea's SK Hynix, alongside Samsung and US-based Micron, have seen their production capacities entirely booked through the end of 2027. The leverage in the semiconductor supply chain has notably broadened; while Nvidia remains the undisputed king of AI logic chips, the memory manufacturers have successfully positioned themselves as indispensable gatekeepers to the AI revolution, commanding premium margins that are ultimately passed down to the final rack price.[1][3]
For the "hyperscalers"—the massive cloud providers like Microsoft, Google, and Amazon Web Services—the $7.8 million sticker shock is forcing a recalibration of capital expenditure strategies. A standard data center cluster required to train a next-generation frontier model often links together thousands of these racks. At current pricing, a state-of-the-art 32,000-GPU cluster now represents a multi-billion dollar infrastructure investment. Despite the eye-watering upfront costs, these companies are purchasing the racks as fast as they can be produced, driven by the existential need to maintain leadership in the generative AI arms race.[2]
The justification for these massive purchases lies in the concept of Total Cost of Ownership (TCO). While a single $7.8 million rack is vastly more expensive than its predecessors, it packs significantly more computational power into the same physical footprint.
This hyper-density is crucial because data center real estate, power provisioning, and the specialized liquid cooling required to keep these systems running are all becoming scarce resources. By concentrating more compute into fewer racks, cloud providers can actually reduce their per-calculation energy costs and minimize the expensive optical networking cables needed to tie the servers together.[2]
However, the soaring cost of entry is having a profound impact on the broader AI ecosystem. For artificial intelligence startups and mid-sized research labs, purchasing their own hardware clusters has become financially impossible. Instead, these organizations are entirely reliant on renting compute time by the hour from the major cloud providers. This dynamic is cementing a hierarchical structure within the tech industry, where a few well-capitalized giants own the physical infrastructure, and everyone else operates as a tenant on their supercomputers.
Looking ahead, the industry is already racing to engineer its way out of the memory cost trap. Hardware startups and established chipmakers alike are exploring alternative architectures, such as optical interconnects that use light to move data, or entirely new processor designs that attempt to bypass the need for HBM altogether. Until those experimental technologies mature, however, the $7.8 million AI rack stands as a testament to the sheer physical and economic scale required to push the boundaries of artificial intelligence in 2026.
Viewpoints in depth
Hyperscale Cloud Providers
View the $7.8 million racks as necessary, efficiency-driving investments that ultimately lower the cost per calculation despite the high upfront price.
For the giants of cloud computing, the sticker shock of a $7.8 million server rack is secondary to the metrics of density and efficiency. Data center real estate is finite, and the power grid connections required to run them take years to secure. By purchasing hyper-dense racks, hyperscalers can pack vastly more computational power into their existing facilities. They argue that while the capital expenditure is historic, the Total Cost of Ownership (TCO) per AI calculation is actually decreasing, allowing them to offer cheaper inference costs to their end users.
Hardware Analysts
Focus on the supply chain bottlenecks and the engineering marvel of High-Bandwidth Memory that justifies the massive premium.
Industry analysts view the pricing shift as a natural consequence of the semiconductor industry hitting the physical limits of traditional chip design. Because data cannot move fast enough over standard motherboards to feed modern AI processors, memory must be stacked and bonded directly to the logic chips. Analysts point out that this 'advanced packaging' is an engineering marvel with inherently low manufacturing yields. From this perspective, the 25% cost share for memory isn't price gouging; it is an accurate reflection of the extreme difficulty of manufacturing the only component capable of keeping AI models fed with data.
AI Startups
Express concern that the soaring cost of physical infrastructure is centralizing power and forcing smaller players into perpetual rental models.
Founders and researchers outside of the major tech conglomerates view the $7.8 million rack as a formidable barrier to entry. In previous tech cycles, a well-funded startup could build its own infrastructure to compete with incumbents. Today, assembling a competitive AI training cluster requires billions of dollars in hardware alone. This camp argues that the sheer cost of next-generation compute is forcing the entire AI ecosystem into a feudal dynamic, where startups must hand over massive portions of their venture capital to rent server time from the very tech giants they are trying to disrupt.
Key points
- Nvidia's next-generation AI server racks have reached a price of $7.8 million per unit.
- High-Bandwidth Memory (HBM) now accounts for roughly 25% of the total system cost.
- Memory manufacturers like SK Hynix and Micron are sold out of top-tier HBM through 2027.
- The high upfront costs are offset for cloud providers by massive gains in compute density and power efficiency.
What we don’t know
- Whether emerging optical interconnect technologies will successfully bypass the need for expensive HBM in future generations.
- How long the current memory supply shortage will last before new manufacturing facilities come online.
- If the massive capital expenditures by cloud providers will ultimately be justified by long-term AI software revenues.
How we got here
Early 2023
Generative AI boom triggers a massive surge in demand for standard data center GPUs.
Mid 2024
Memory bottlenecks become the primary limiting factor in training larger AI models.
Late 2025
Memory manufacturers announce they are entirely sold out of advanced HBM capacity.
June 2026
Next-generation AI racks hit the market at $7.8 million, with memory driving a quarter of the cost.
- Hyperscale Cloud Providers
- View the $7.8 million racks as necessary, efficiency-driving investments that ultimately lower the cost per calculation despite the high upfront price.
- Hardware Analysts
- Focus on the supply chain bottlenecks and the engineering marvel of High-Bandwidth Memory that justifies the massive premium.
- AI Startups
- Express concern that the soaring cost of physical infrastructure is centralizing power and forcing smaller players into perpetual rental models.
Perspectives this story doesn't cover
- Environmental Advocates
- Open-Source AI Developers
Sources
Source coverage
3 outlets
3 viewpoints surfaced


- [1]ReutersAI Startups
Nvidia's latest AI server racks price at $7.8 million amid memory supply crunch
Read on Reuters → - [2]BloombergHyperscale Cloud Providers
Hyperscalers Brace for Impact as Nvidia's Next-Gen Compute Costs Surge
Read on Bloomberg → - [3]CNBCHardware Analysts
Micron stock jumps 9% as soaring prices from memory crunch lead to quadrupling of revenue
Read on CNBC →
More in Artificial Intelligence
See all →Agentic Finance
European Bank Becomes First to Allow External AI Agents to Trade Live Brokerage Accounts
3 sources
AI Hardware
Cerebras Unveils CS-4 Wafer-Scale AI System, Claiming 30x Faster Inference Than GPUs
7 sources
AI Hardware
How Nvidia's RTX Spark Architecture Shifts AI Processing to Local PCs
3 sources
AI Leadership
DeepMind CEO Demis Hassabis Steps Down to Focus on 'Big Picture' AGI Strategy
4 sources
Comments
Every angle. Every day.
Get Artificial Intelligence stories with full source coverage and perspective breakdowns, free every day.