full timeline
Nvidia Vera Rubin AI platform rollout
Follow Nvidia Vera Rubin AI platform rollout in the Factlen app and get an alert when there is news. Get the app
Share this story
Latest
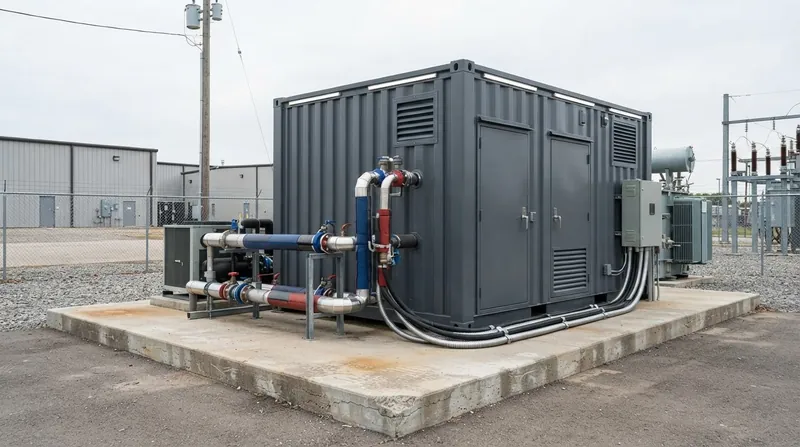
By 12:27 UTC on October 27, Nvidia unveiled its modular DSX POD containers, a reference design intended to reduce AI factory deployment times from months to as little as 14 days. The containerized system houses 504 Rubin GPUs across seven Vera Rubin racks, shifting rack integration, liquid cooling, cabling, piping, and testing into manufacturing facilities rather than onsite builds.
Achieving the 14-day deployment target requires destination sites to have power generation, cooling water, and network connectivity already prepared.
Prior to this hardware deployment shift, by 21:55 UTC on October 22, Google Cloud and Nvidia launched general availability for the Vera Rubin AI infrastructure through new A5X instances. The Google Cloud deployment scales up to 960,000 networked GPUs to meet the memory demands of autonomous AI agents. The rollout involved deep co-engineering to integrate Nvidia's networking and silicon into Google's liquid-cooled data centers, and Nvidia shares climbed over one percent following the announcement.
How the story developed
By 18:42 UTC on August 6, Nvidia introduced the Vera Rubin AI architecture, marking a shift in AI infrastructure from compute-bound to memory-bound design. The platform integrates a custom CPU and GPU into a unified rack-scale system.
The architecture was designed to drastically lower the cost of running complex agentic models. It utilizes HBM4 memory and NVLink 6 technology to eliminate traditional data movement bottlenecks.
By addressing these bottlenecks, the system promises a tenfold reduction in the cost of generating AI inference tokens. Additionally, training complex Mixture-of-Experts models on the new platform requires four times fewer GPUs compared to the previous generation.
At the time of the August unveiling, full production systems were projected to reach cloud providers in the second half of the year. This transition from announcement to availability materialized in late October with the initial cloud deployments and the introduction of containerized physical infrastructure.
What to watch
- Hardware partners including Dell, HPE, and Lenovo are expected to begin delivering the modular factories in early 2027.
Key numbers
From: Nvidia Unveils Vera Rubin AI Architecture, Promising 10x Inference Cost Reduction
Charts, maps and images
Timeline
October 2026
Nvidia Unveils Modular DSX POD Containers to Shrink AI Factory Deployment to 14 Days
Google Cloud and NVIDIA Launch Vera Rubin AI Infrastructure for General Availability
August 2026
Nvidia Unveils Vera Rubin AI Architecture, Promising 10x Inference Cost Reduction